Cloud Monitoring Observability
A monitoring stack for logs, metrics, alerts, and service health across cloud workloads.
Project Description
What I delivered for this project.
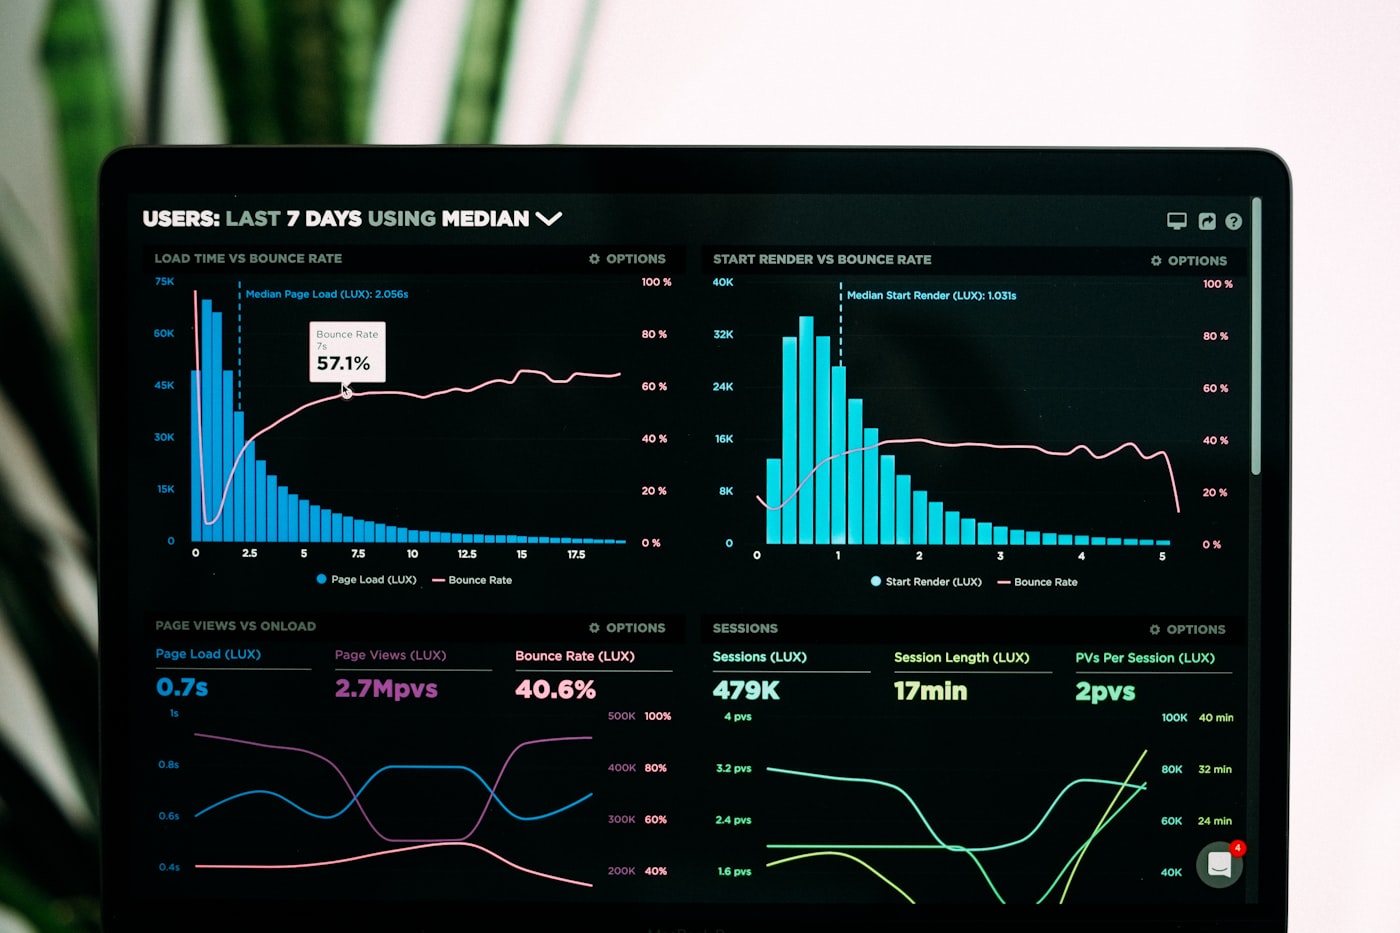
I connected infrastructure metrics, logs, dashboards, and alert rules into a practical observability stack that helps teams detect and investigate incidents sooner.
Overview
A focused system for practical operations.
This observability setup gives teams a clearer view of infrastructure health, application performance, resource usage, and incident signals.
Important failures were hard to diagnose because logs, metrics, and alerts were scattered across separate tools and manual checks.
Solution
What changed in the final workflow.
I configured dashboards, service-level alerts, log views, and infrastructure metrics so problems could be detected and investigated faster.
The lab demonstrates centralized operational visibility and a practical foundation for incident-response and reliability reviews.
Implementation Gallery
Selected infrastructure and delivery views.